PreText
Introduction
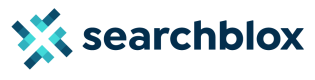
Website data often exists in different formats, which makes it difficult to collect and understand the actual content. People may interpret the same page in different ways, and the variety of data formats can make traditional data ingestion methods less effective. Pretext NLP helps solve this problem by enriching metadata and enabling search from multiple perspectives. It uses AI models to convert raw data into meaningful knowledge by analyzing large amounts of information.
Architecture
SearchBlox PreText NLP can generate AI-driven machine learning fields such as ml_title, ml_description, ml_topic, ml_sentimentLabel, ml_sentimentScore, ml_entity_org, ml_entity_product, ml_entity_person, ml_entity_loc, and ml_entity_gpe.
Create PreText NLP Endpoint
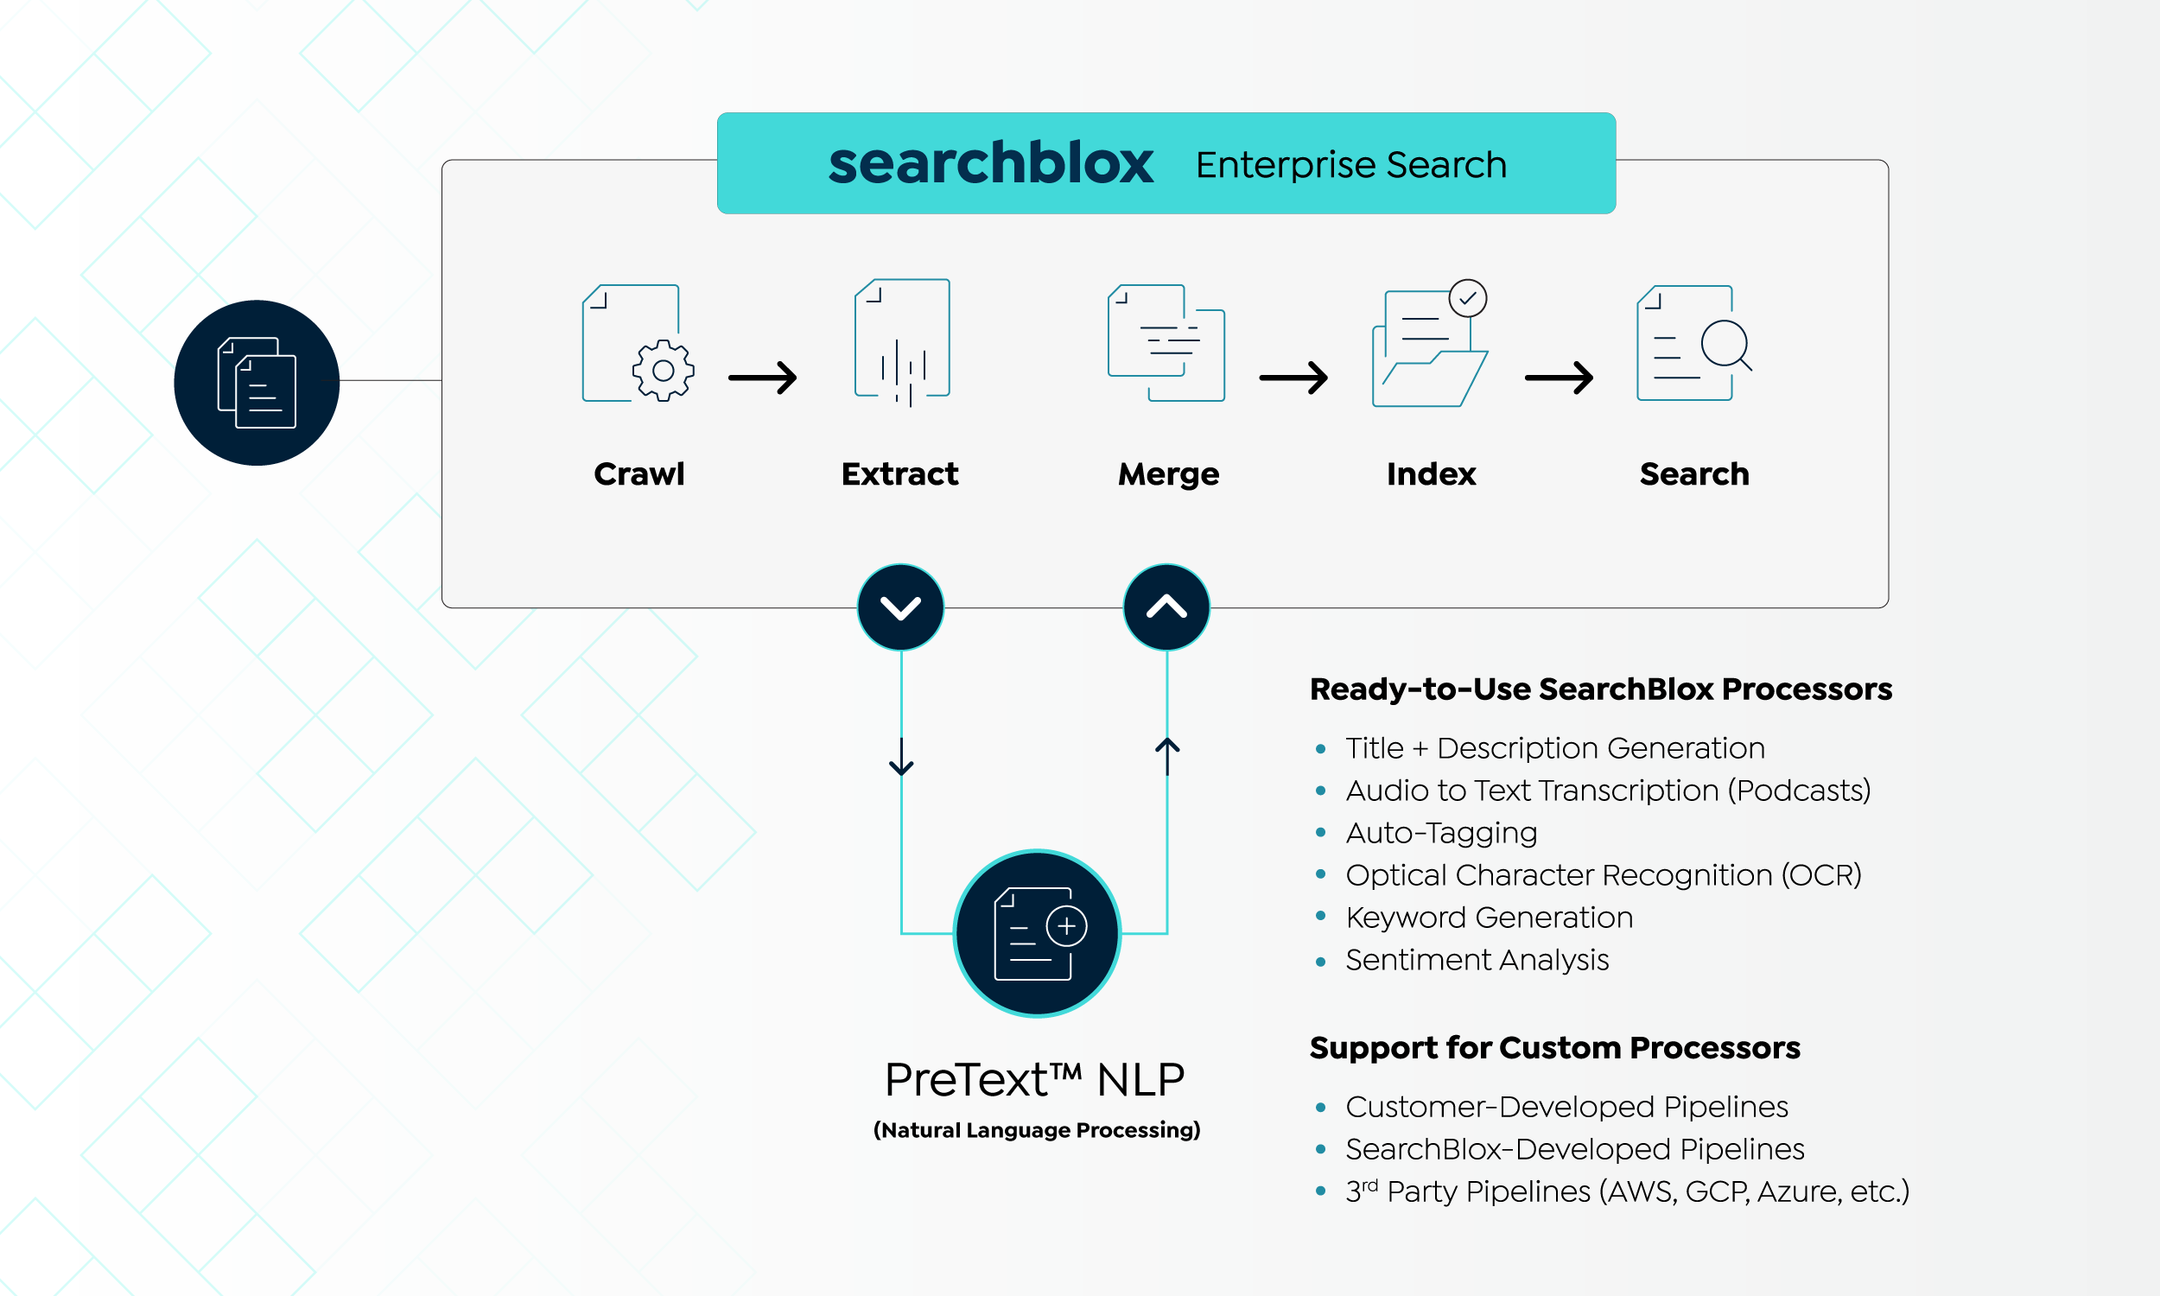
You can sign up for a FREE SearchBlox PreText NLP account using the following link: https://pretext.searchblox.com/
You can also access the PreText account signup link directly from the PreText screen.
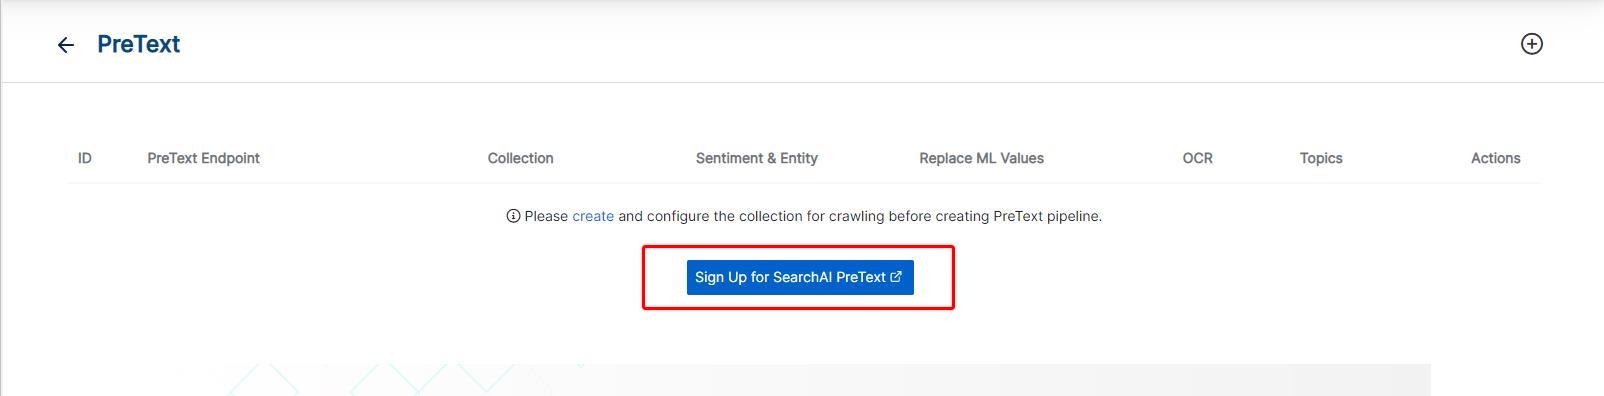
Provide the PreText account details as shown in the screenshot below:
Once you click the Create an account now button, an activation email will be sent to you. Open the email, click the activation link, and upon successful activation, the Login Page will appear.
Important:
If Activation of account is not successful, you will be able to login, but creation of endpoint will fail.
PreText login screen:
After logging in to your FREE PreText account, the PreText Dashboard appears. From there, you can create a PreText pipeline for integration with the SearchBlox Enterprise Application by clicking Create Pipeline..
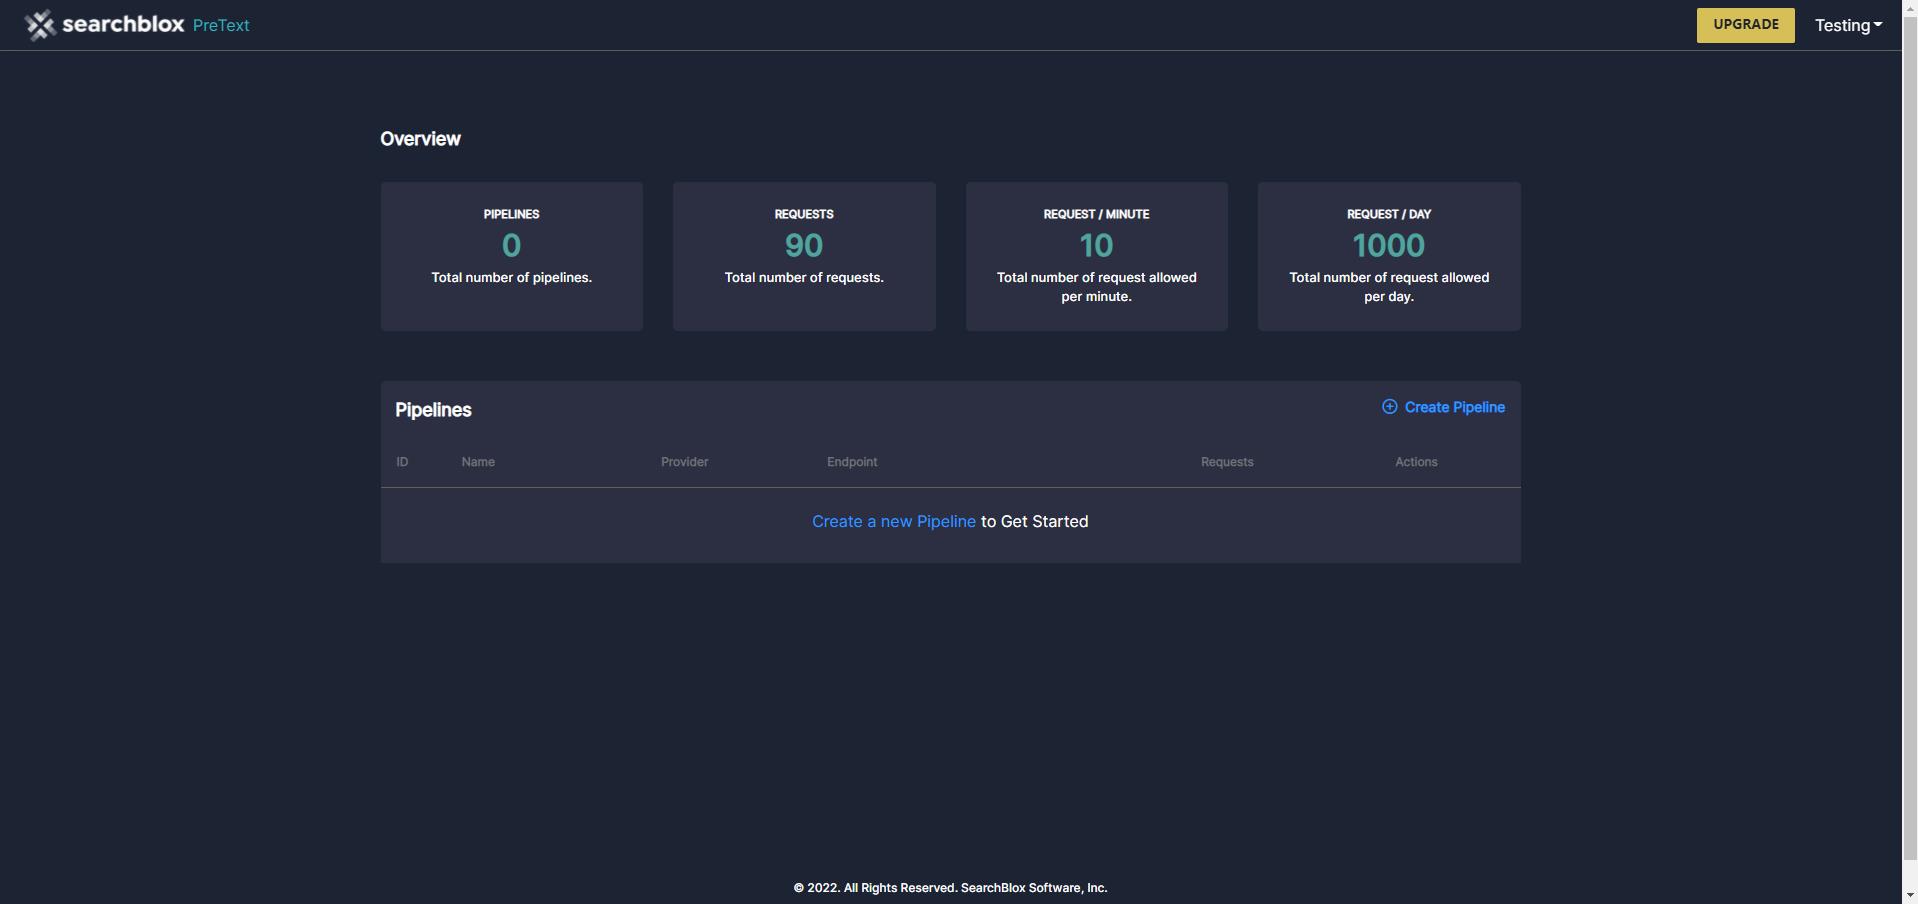
Create SearchBlox PreText Pipeline
Choose the provider as SearchBlox once you click on Create Pipeline.
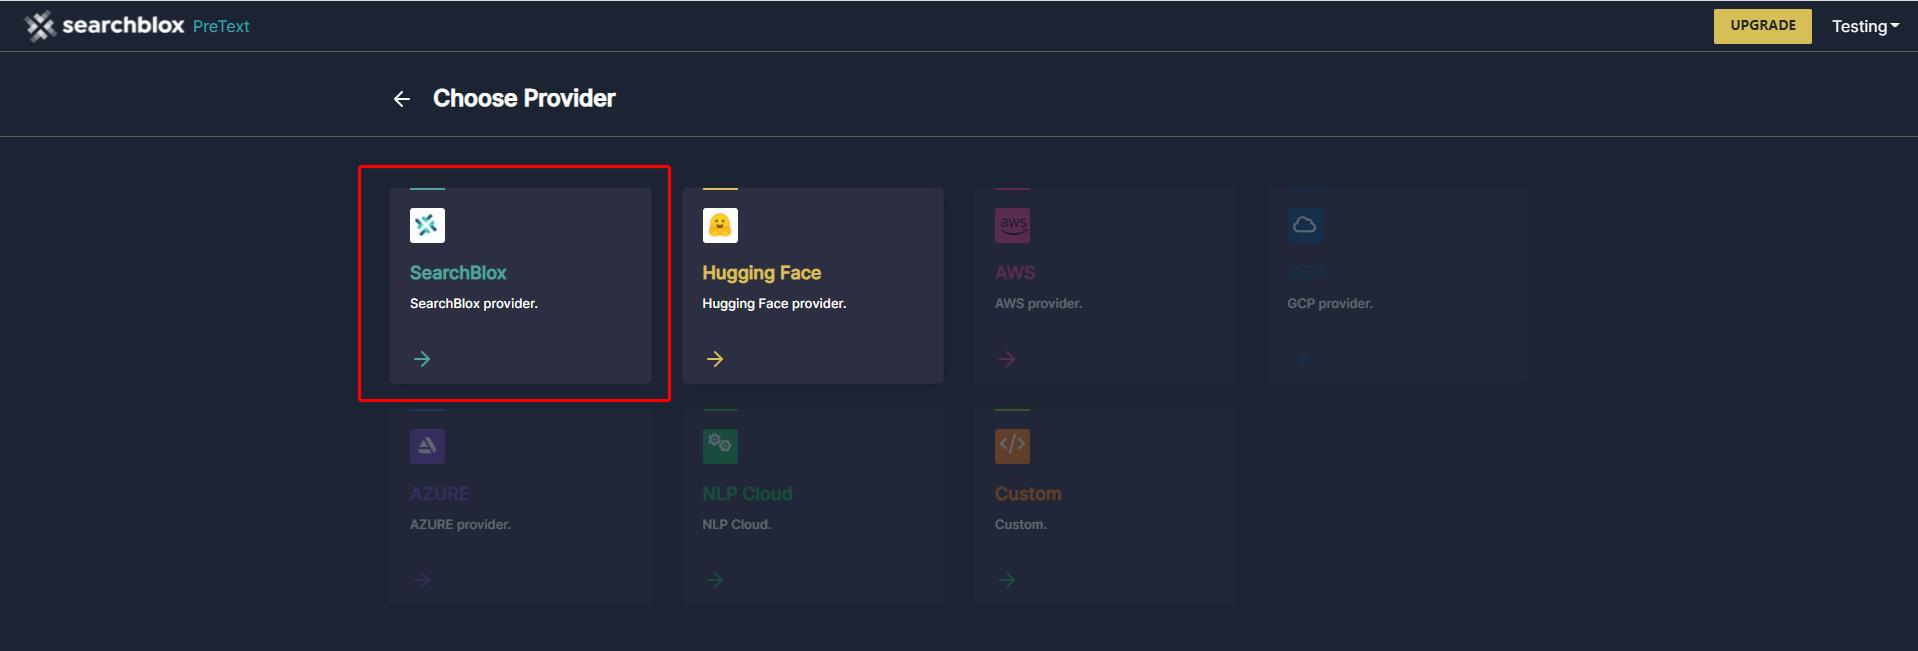
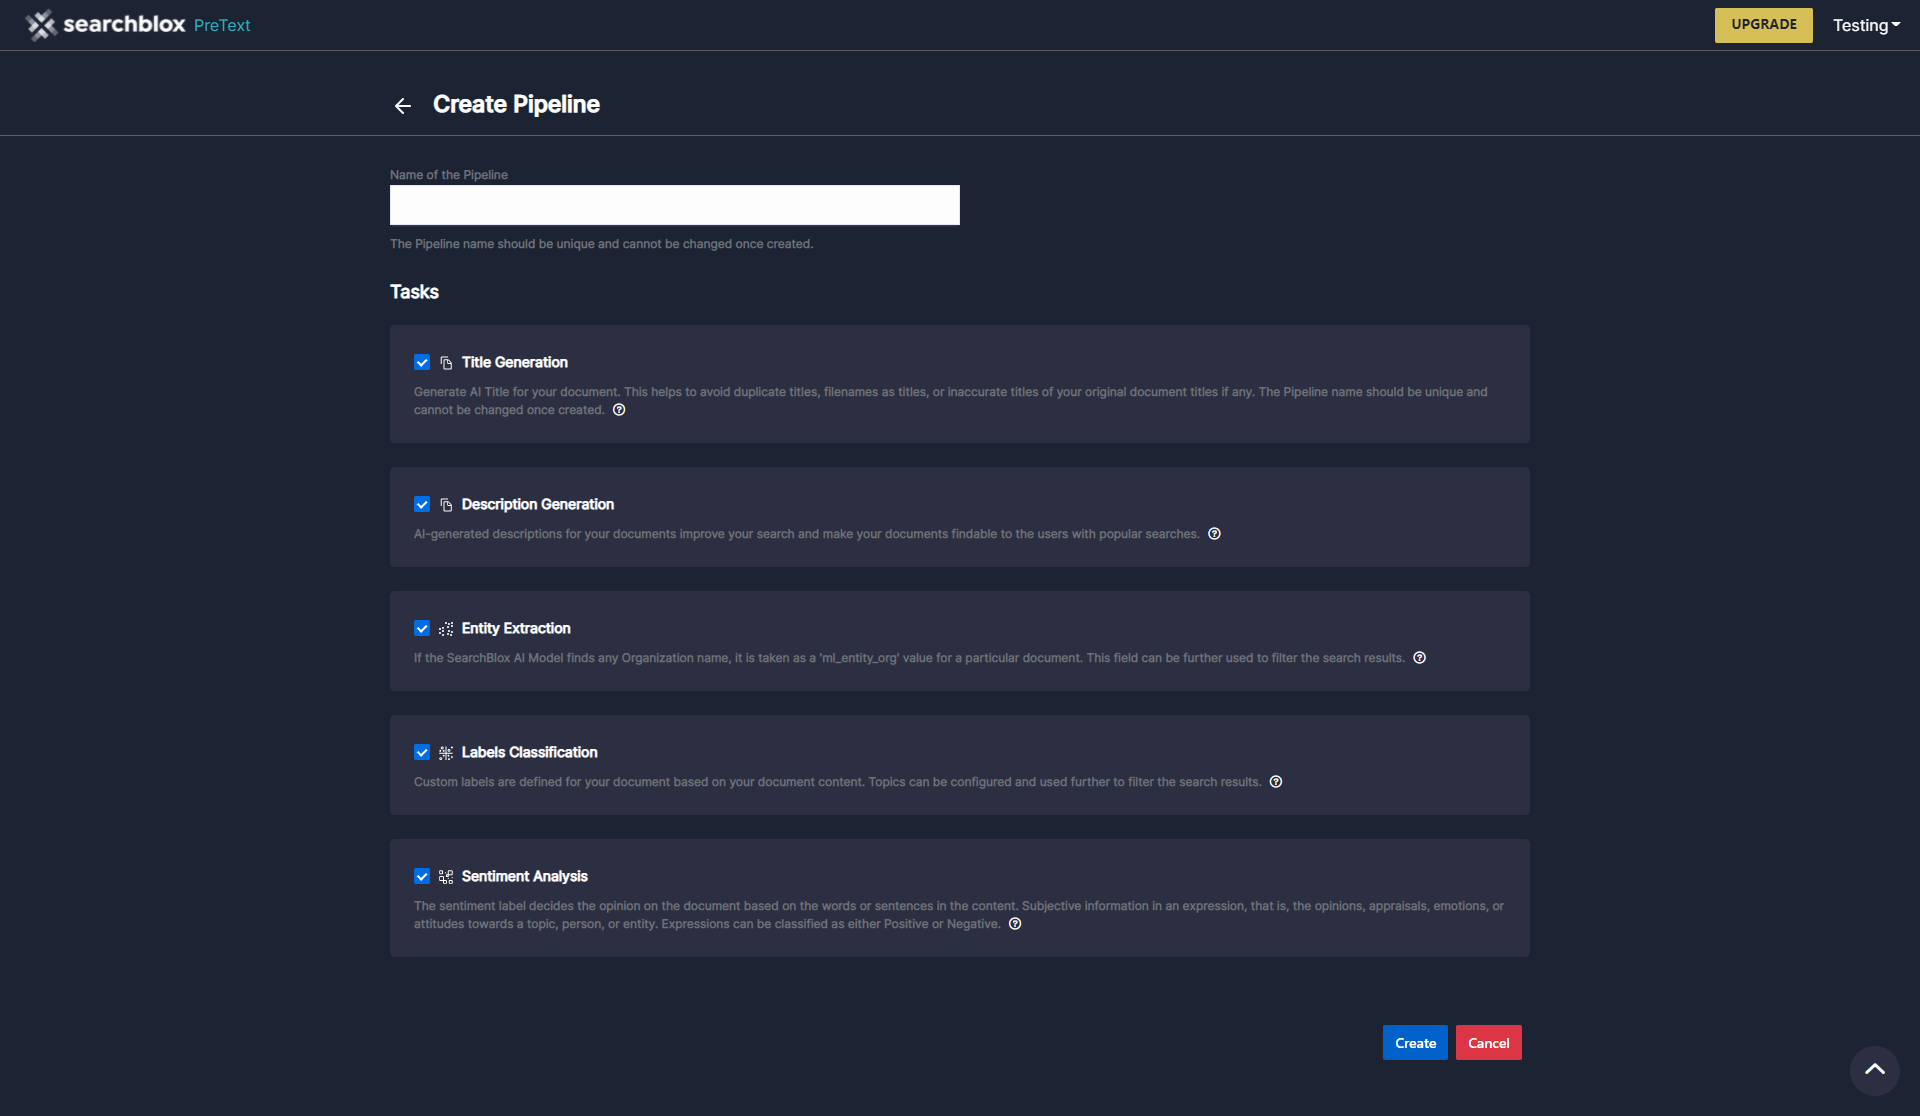
Enter a name for the SearchBlox PreText Pipeline and select the tasks you want to integrate with the SearchBlox collection. By default, all tasks are already selected.
Integration with Hugging Face API using PreText Pipeline
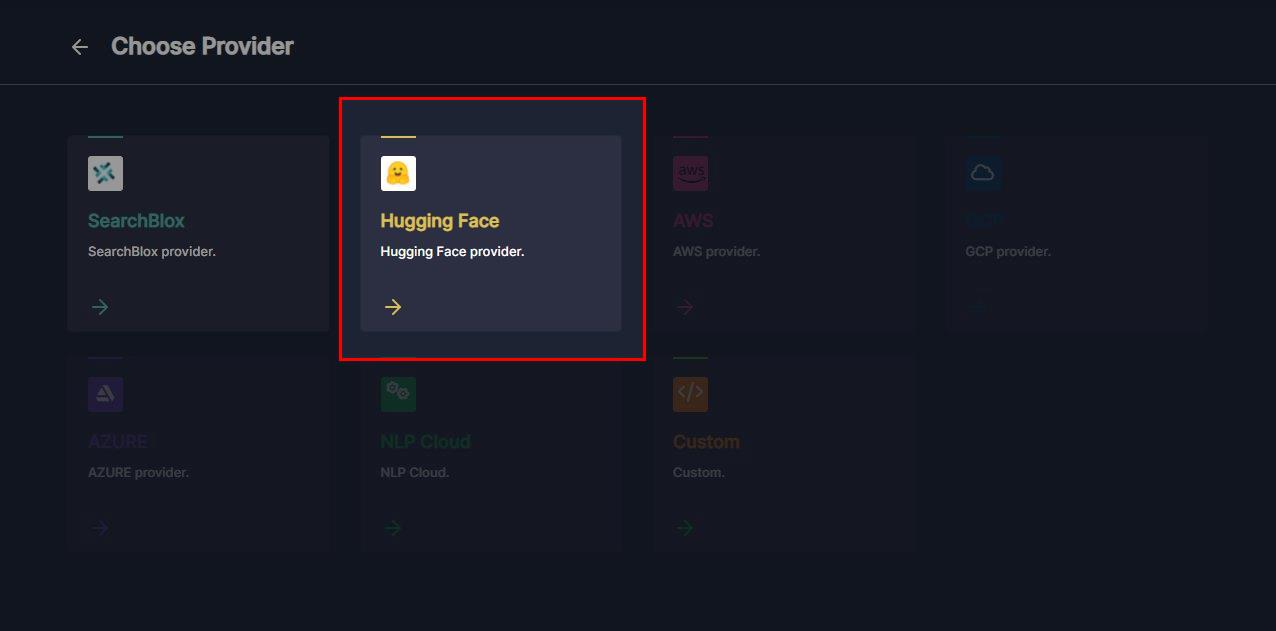
Youcan configure the Hugging Face API in the PreText Pipeline and integrate it with your SearchBlox collection. To begin, select Hugging Face as the provider.
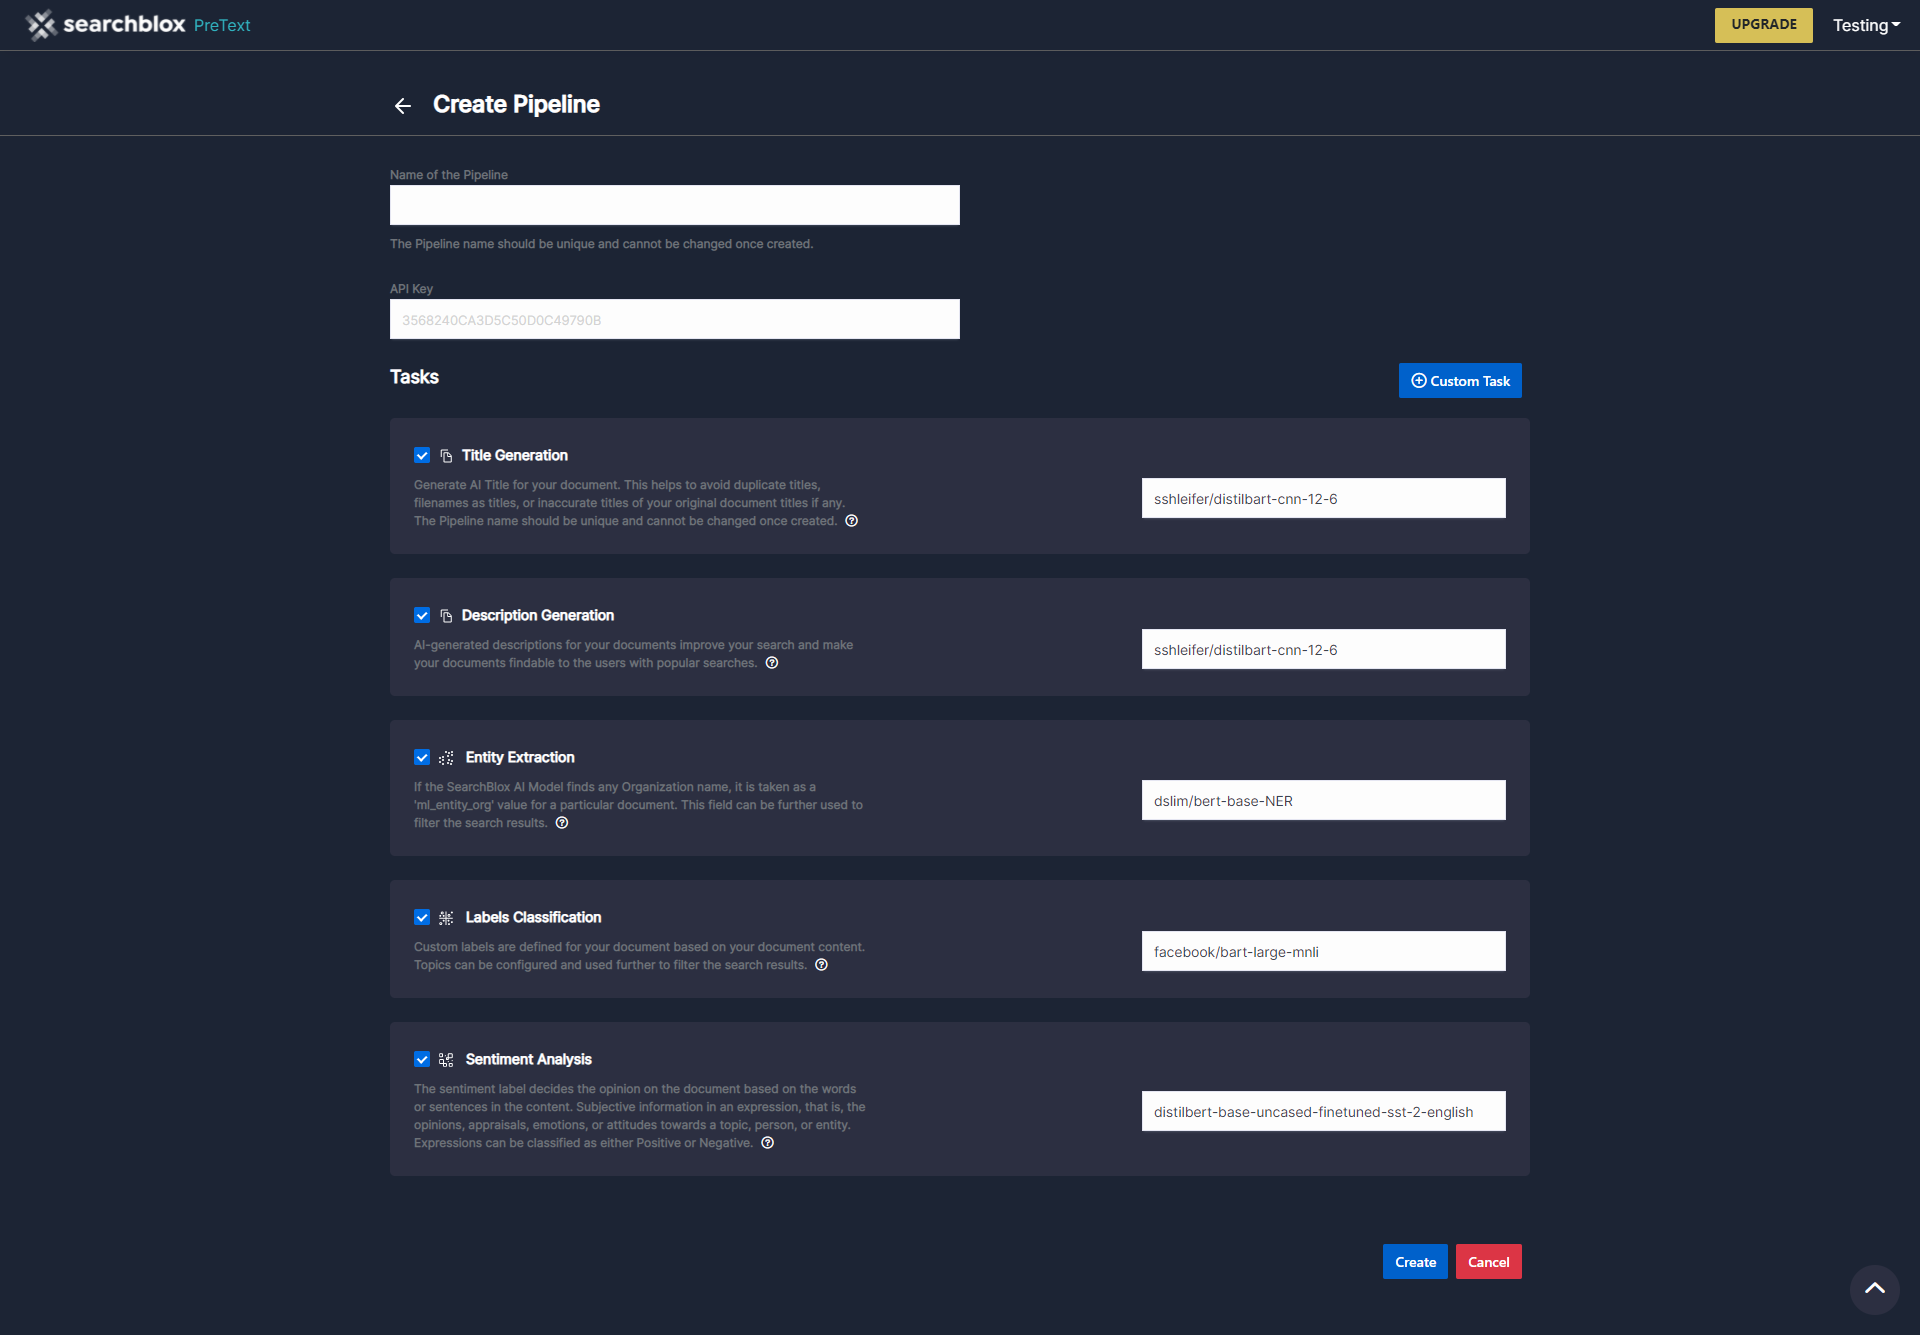
This configuration requires the Hugging Face API for integration and a unique name to identify it in SearchBlox. You can then select the tasks you want to enable; by default, all tasks are already selected.
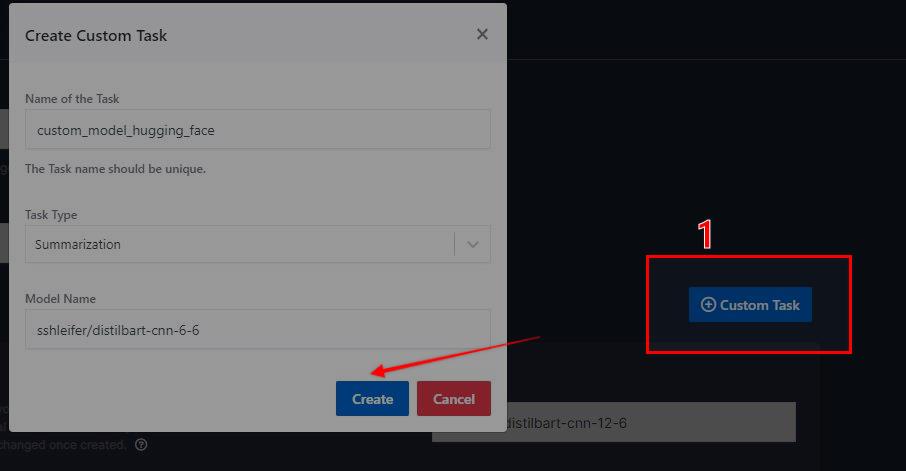
Using the Hugging Face pipeline, you can also create custom tasks for integration with SearchBlox. When creating a custom task, provide a unique name, select the task type from the available list, and choose the model name from the type-ahead Hugging Face model suggestions. After creating the custom task, make sure it is selected in the pipeline screen.
Once you create the pipeline, you can see the pipeline in the PreText Dashboard.
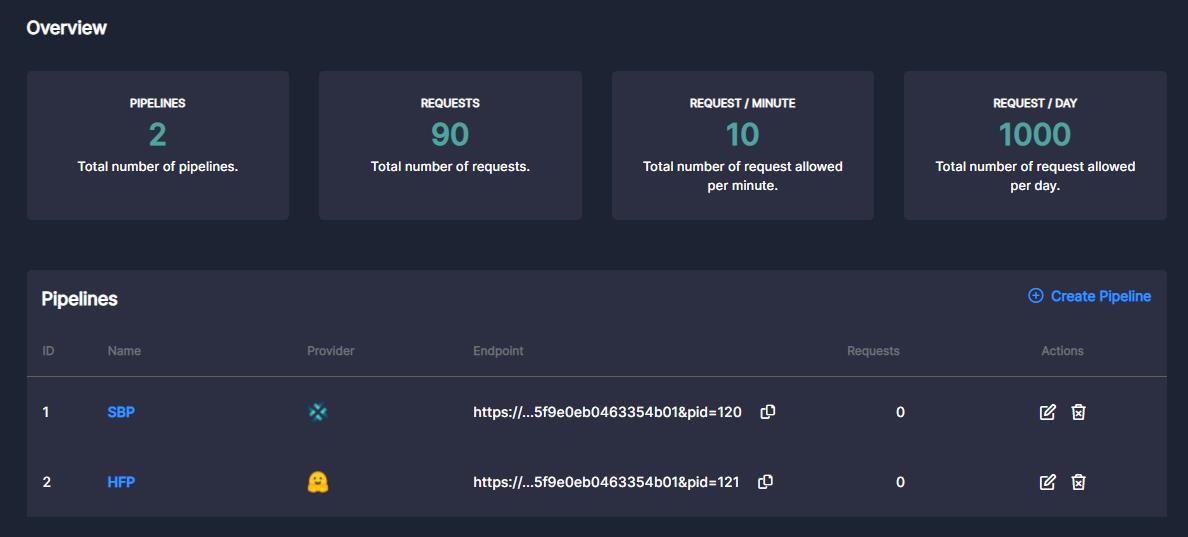
Copy the pipeline endpoint to integrate it with SearchBlox Collection.
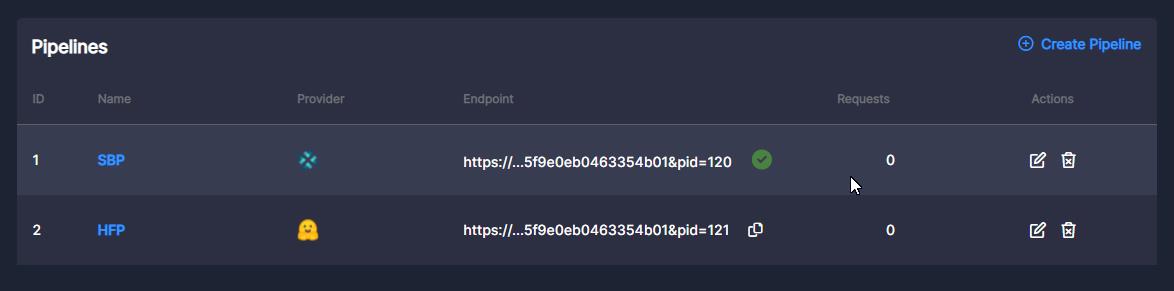
NOTE:
PreText NLP FREE account has limitations. To upgrade to the premium services, please contact SearchBlox Support.
Configure PreText Pipeline
- Create a SearchBlox collection before configuring the PreText pipeline. PreText supports all SearchBlox collection types, and this applies to both SearchBlox and Hugging Face pipeline endpoints.
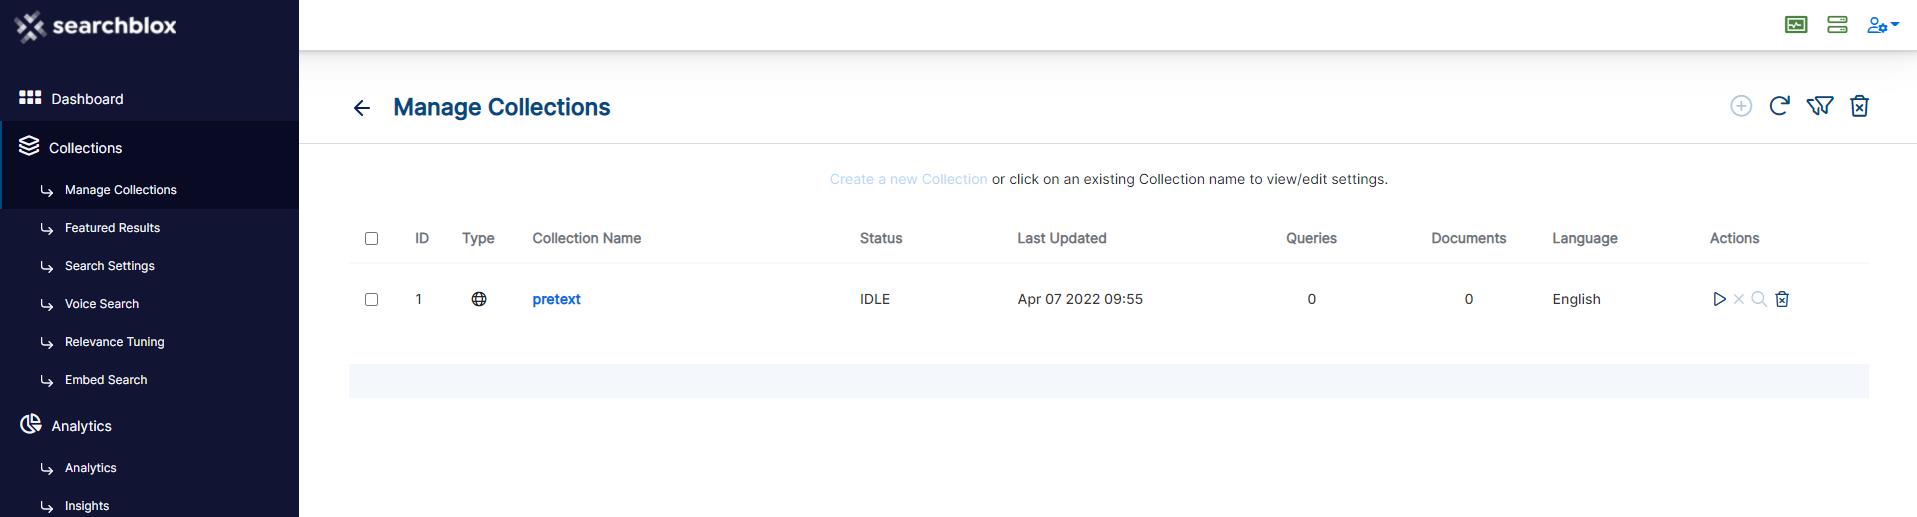
- On the Menu Bar, click Search AI and select PreText to access and use the pipeline.
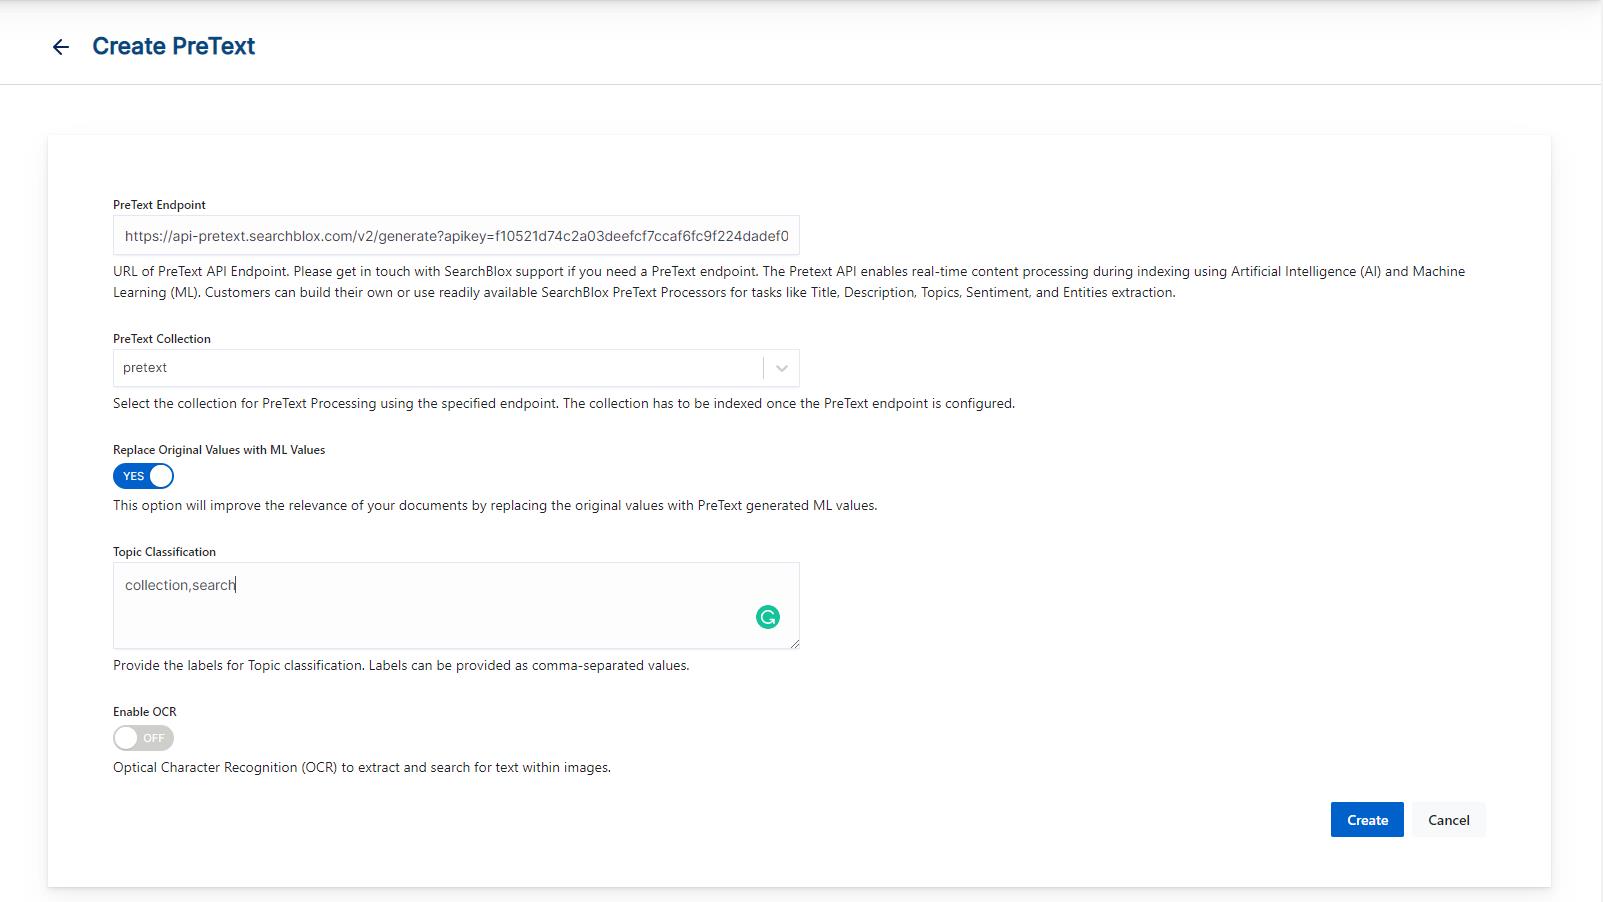
- Provide the following details to apply the pipeline’s functionality to your collection:
a. Enter the PreText endpoint copied from your PreText account.
b. Select the collection to which you want to apply the AI pipeline.
c. For the first run, keep the Replace ML Values option turned off. When enabled, SearchBlox automatically maps the ML Title and ML Description to the Search Title and Search Description fields.
d. Add Topic Classification labels if you want to generate the ml_topic metadata field.
e. Enable OCR to allow PreText to process text from image-based documents such as JPG, PNG, and PDF.
Finally, click the Create button to create your PreText pipeline.
Note:
OCR feature has a dependency on Tesseract Software. Please find the OCR Reference:
https://developer.searchblox.com/v9.2.3/docs/filesystem-collection#ocr-recognitionto install/update Tesseract in your machine.
- Start reindexing your collection after you configure the PreText endpoint with collection
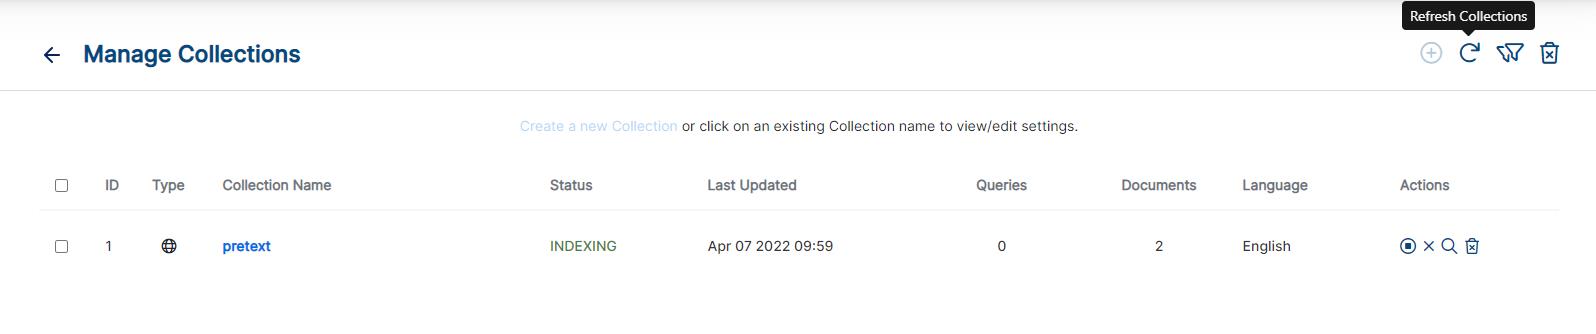
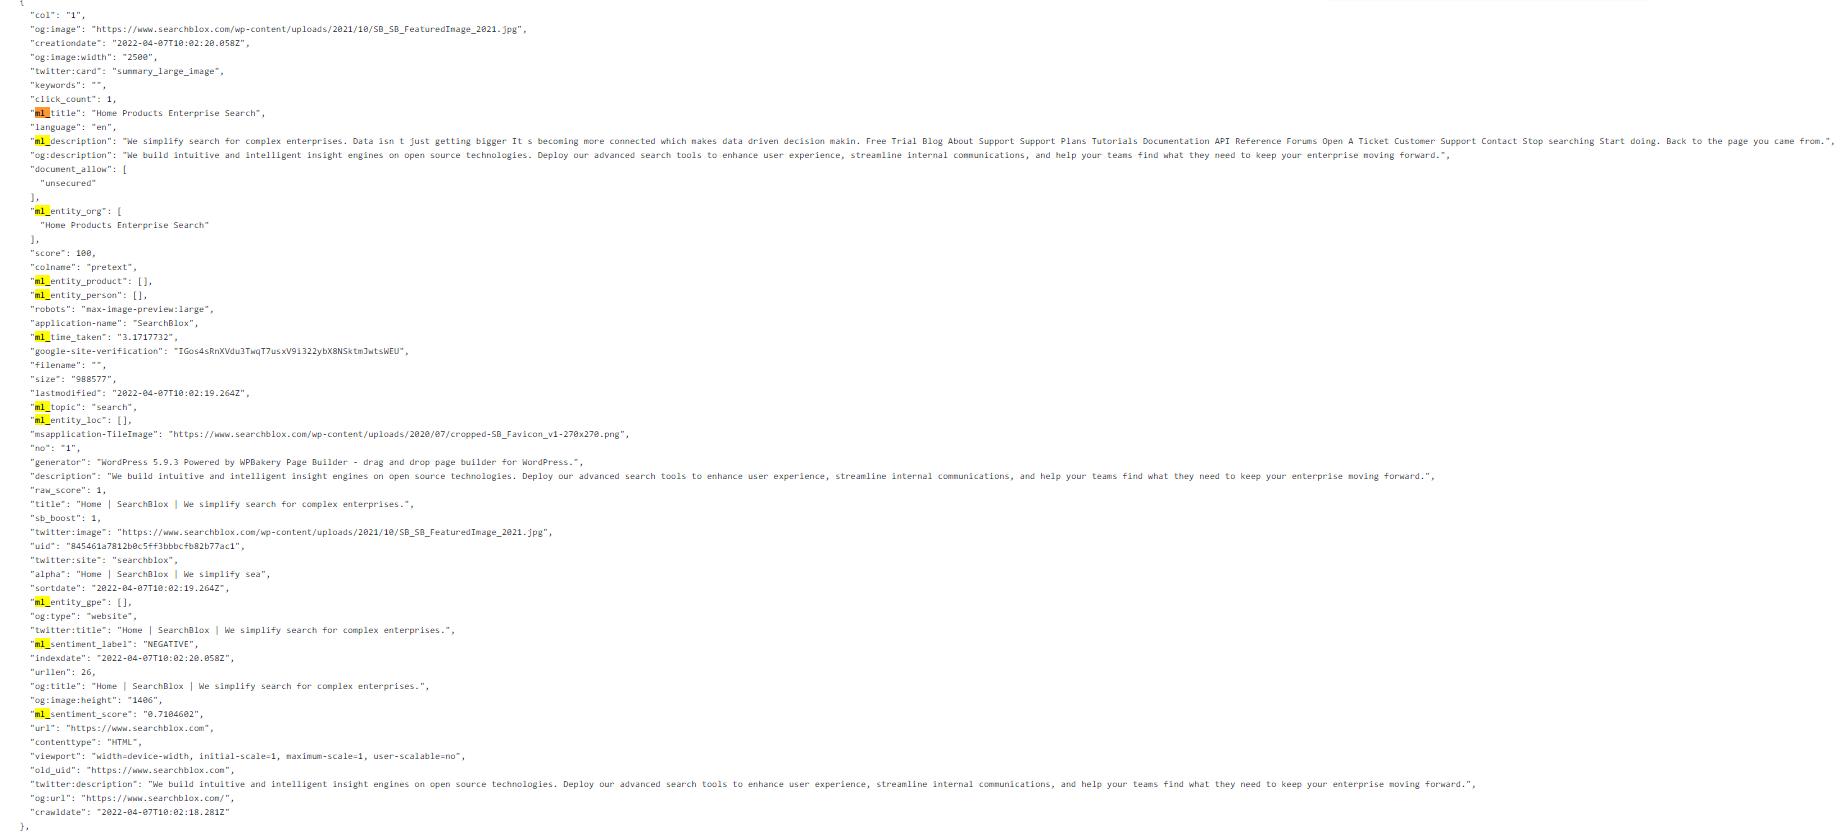
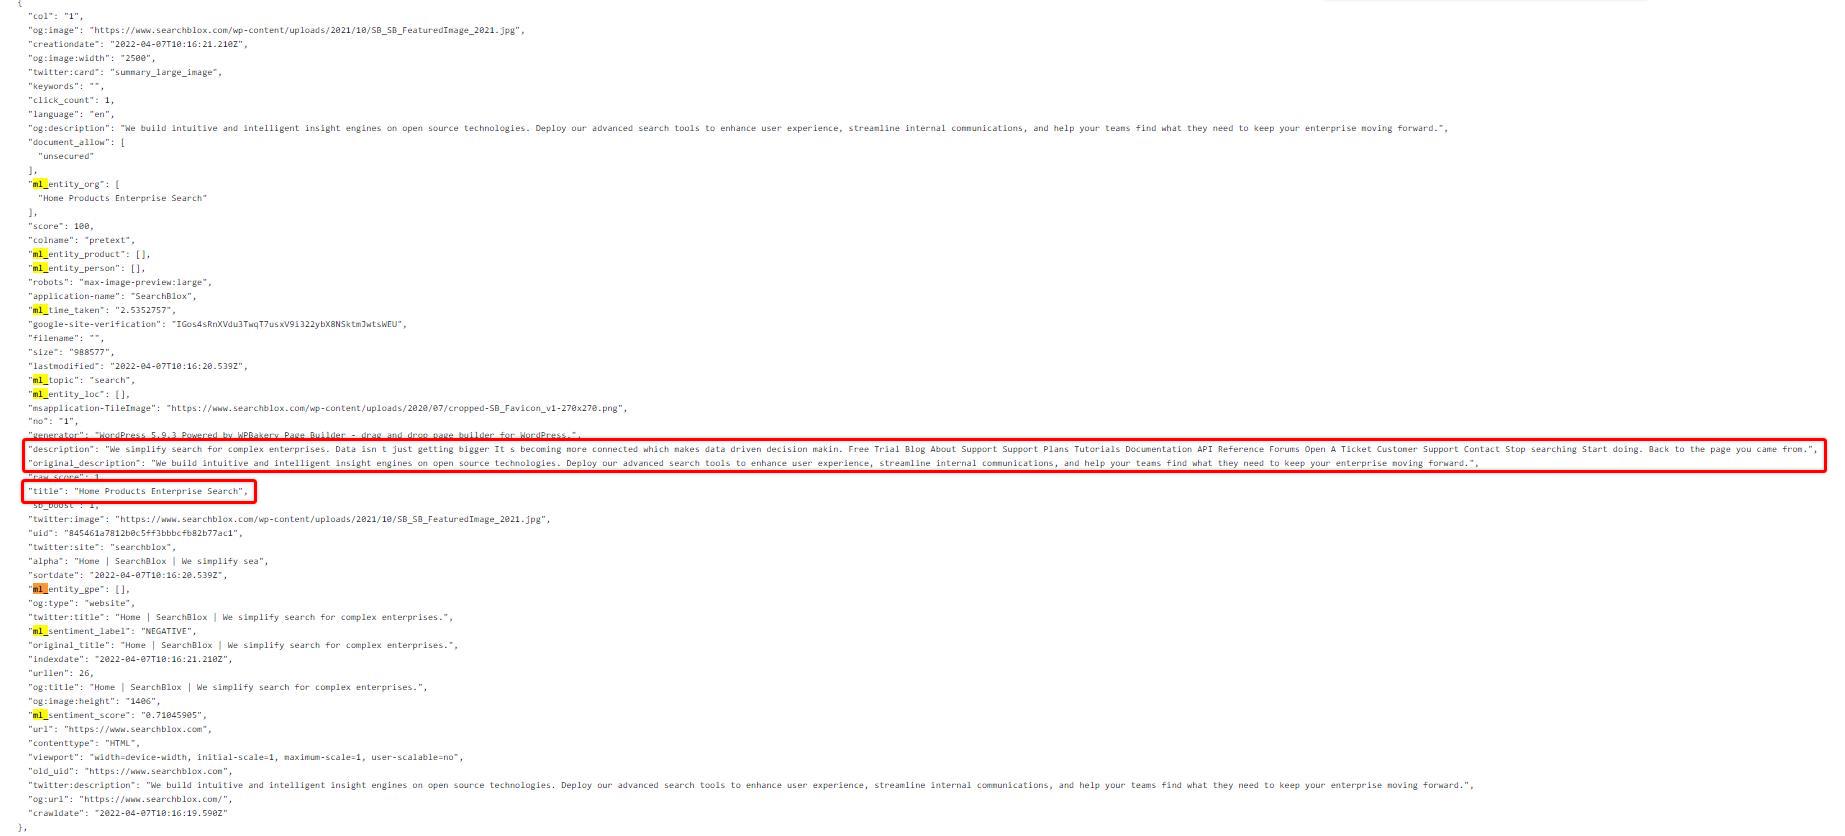
- You can view the AI-generated title and other ml_fields while performing a search in debug mode. To see the PreText-generated fields in your search results, add &debug=true to the search URL. This will display the complete JSON response, including all AI-generated metadata.
Below is the screenshot when the PreText setting “Replace Original Values with ML Values” is set to OFF.
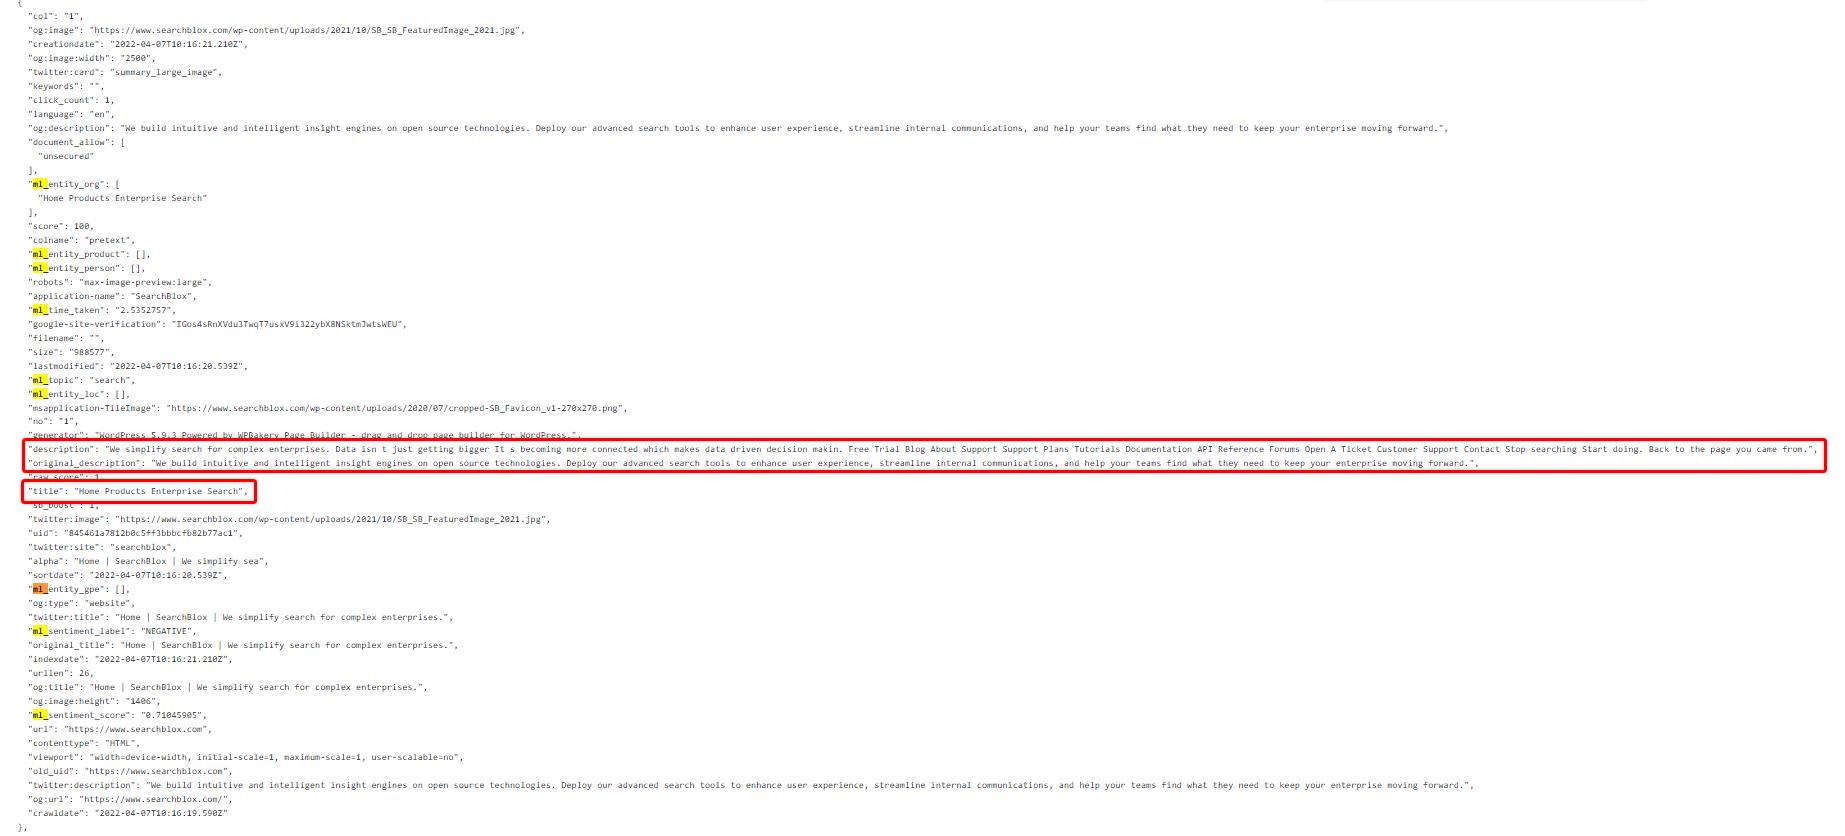
_Below is the screenshot when the PreText setting “Replace Original Values with ML Values” is set to ON. In this case, the original document title and description are replaced with the ML Title and ML Description values in the debug mode search response. The remaining ML fields will be displayed as they are.
PreText Search UI
You can access PreText search UI using https://localhost:8443/pretext/index.html
Select the PreText UI Template to view ML values:
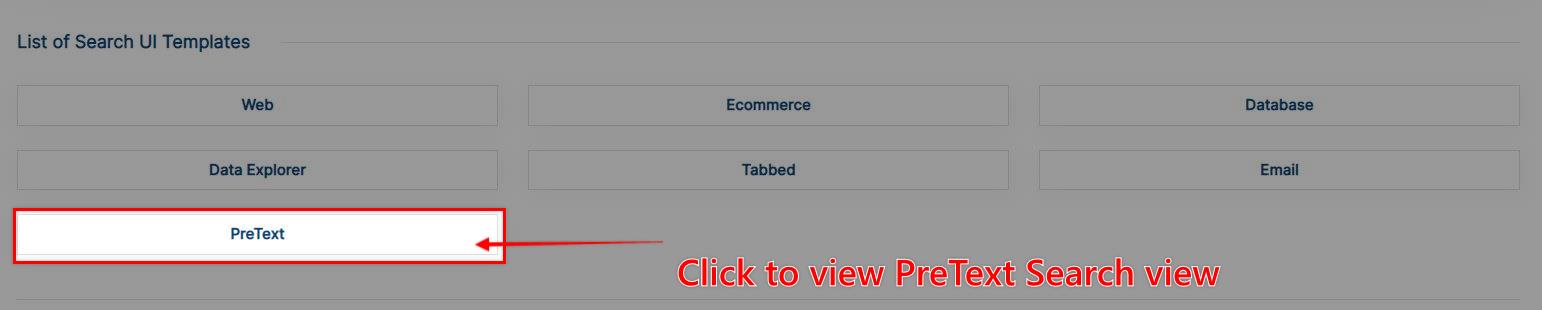
-
- With Replace ML Values enabled, the PreText UI displays all documents with AI-generated titles and descriptions, along with ML facets such as Topic, Sentiment, and Entities. The original titles and descriptions remain available as the actual document metadata.
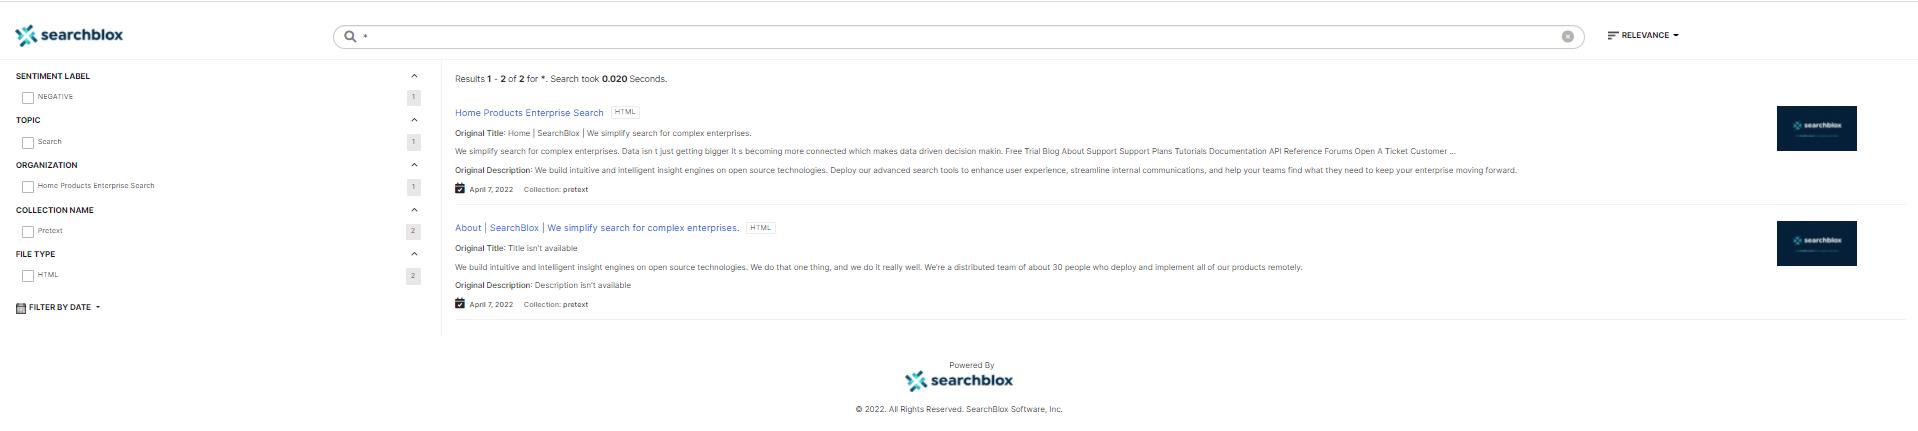
Note
You can disable the display of Original Title and Original Description in the PreText UI by setting original_title and original_desc to false in the .../webapps/ROOT/pretext/index.html file.
These settings can also be configured in facet.js using the originalTitle and originalDesc properties. The index.html configuration takes priority over the facet.js settings.
You can temporarily control the display using URL parameters: &originalTitle and &originalDesc. Set them to true to show the Original Title and Original Description, or false to hide them in the PreText Search UI.
- PreText UI with Replace ML Values OFF displays all documents with AI-generated ML Titles and ML Descriptions, along with ML facets such as Topic, Sentiment, and Entities when the ML Replace setting is enabled. You can also view the original document titles and descriptions, allowing you to compare them directly with the ML-generated versions on the PreText Search page.
PreText Debug Log
You can find the pretext.log file in the following path:
/webapps/ROOT/logs/
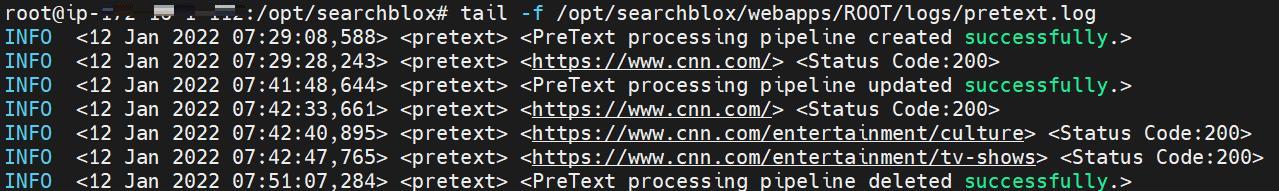
PreText Basic Log:
The basic log information in pretext.log includes details about the PreText pipeline, such as the PreText request and the corresponding status code. The screenshot below shows an example for reference.
PreText Debug Mode Log:
Append &debug=true to your PreText NLP endpoint during configuration to view detailed processing information for each PreText request. This shows an expanded response that helps you understand how every request is processed, as shown in the reference screenshot.
ERROR CODES
| Status Code | Status Message |
|---|---|
| 400 | Error parsing the body. |
| 500 | Timeout Error. |
| 504 | Gateway Timeout Error. |
| 524 | Server Down. |
Conclusion
SearchBlox provides AI-generated ML fields such as ml_title, ml_description, ml_topic, ml_sentimentLabel, ml_sentimentScore, ml_entity_org, ml_entity_product, ml_entity_person, ml_entity_loc, and ml_entity_gpe for collection documents. These fields help uncover hidden insights and improve searchability with minimal effort.
All ML values are generated from the document’s content, and the SearchBlox AI model automatically determines the appropriate values for each field.
| ML Field | ML Field Description |
|---|---|
| ml_title | AI-generated title for the document that replaces duplicate titles, filenames, or inaccurate original titles. |
| ml_description | AI-generated description that improves search relevance and helps users discover documents more easily. |
| ml_topic | Custom topic labels generated from the document content, useful for filtering search results. |
| ml_sentimentLabel | Indicates the sentiment of the document based on the words or sentences in the content. It analyzes opinions, emotions, or attitudes toward a topic, person, or entity, and classifies them as positive or negative. This field can also be used to filter search results. |
| ml_sentimentScore | A score that represents the tone of the content on a scale from positive to negative. The sentiment label is determined based on this score. |
| ml_entity_org | If the SearchBlox AI model identifies an organization name in the document, it is stored in this field. It can also be used to filter search results. |
| ml_entity_product | If the SearchBlox AI model finds any product information, it is stored as an ml_entity_product value for that document. This field can be used to filter search results. |
| ml_entity_person | If the SearchBlox AI model identifies a person's name, it is stored as an ml_entity_person value for that document. This field can also be used to filter search results. |
| ml_entity_loc | If the SearchBlox AI model detects location information, it is stored as an ml_entity_loc value for that document. This field can also be used to filter search results. |
| ml_entity_gpe | If the SearchBlox AI Model finds any Geo-Political Economy information, it is taken as a 'ml_entity_gpe' value for a particular document. This field can be further used to filter the search results. |
| ml_time_taken | Indicates the total time taken by the PreText service to process the document and generate the ML fields. |
Updated 7 months ago